Brand Guidelines as a Resolvable Service Contract Your Agent Fleet Subscribes to at Inference Time
Agents need to query brand rules at inference time, not copy them into prompts.
Making existing brand guidelines usable by AI agents requires translating them into structured constraints and serving them as a versioned contract that agents resolve at inference time. Model Context Protocol delivers the brand specification to agent workflows. This architecture moves brand consistency from a human-review problem to a systems problem, with shared rules delivered at generation time and output checked against the version used.
Why brand guidelines fail at agent scale before any agent touches them
Guidelines describe what the brand aims for, but agents need explicit constraints they can retrieve and apply to the task at hand. “Friendly but premium” leaves the operative distinction unstated. A rule that specifies professional tone for a social media channel and names banned terms gives the agent a defined instruction and gives review a basis for checking compliance.
Changing the container does not resolve that mismatch. A PDF, a Notion document, and a pasted prompt can all present the same descriptive language without a mechanism for resolving the current rules. Even when a shared document has an edit history, a copied passage does not tell an agent whether it remains authoritative. The agent has text, but no reliable resolution mechanism. Most guidelines sit in slide decks, shared drives, and onboarding documents rather than at an interface an agent can query during generation.
Human approval can compensate for this gap on individual assets, but it does not repair the architecture. A reviewer must supply the interpretation and current knowledge that the agent never received. As more agents produce more kinds of work, that dependency spreads across the fleet. The structural fix therefore begins before output exists, by making brand authority explicit and available at the point of execution.
What a service-contract model for brand guidelines actually means
A brand service contract is a structured specification with three distinct properties, namely resolvability, versionedness, and subscribability. Resolvability means an agent can query the authoritative brand state when it needs it. The agent can work without relying on text someone gave it during configuration. As a REST API serves a structured response to a calling client, a brand service contract serves structured brand context without requiring the agent to understand how that context is stored.
Versionedness makes each change a declared update to the specification. The declared current version governs new resolution calls. Earlier versions remain distinguishable from the rules that replaced them, which gives generation and review a precise reference. Without that distinction, “the brand guidelines” can mean different instructions to different agents.
Subscribability defines the relationship between the agent and that specification. Agents connect once and resolve updates through that connection, so no one has to do manual re-prompting each time a rule changes. Subscription makes the shared specification the authority for brand context.
That authority also needs a defined scope. The contract specifies which agents may query which brand elements, under what conditions and with what guardrails. Mayer Brown’s October 2026 analysis of agentic AI contracting warns that when responsibilities are unclear, providers can be held responsible for what autonomous agents do through warranties, implied duties, or negligence standards. It recommends a detailed scope schedule that puts this technical boundary into the terms of how the work is done. Access to brand context is an authorization decision.
How MCP makes brand guidelines resolvable across an agent fleet
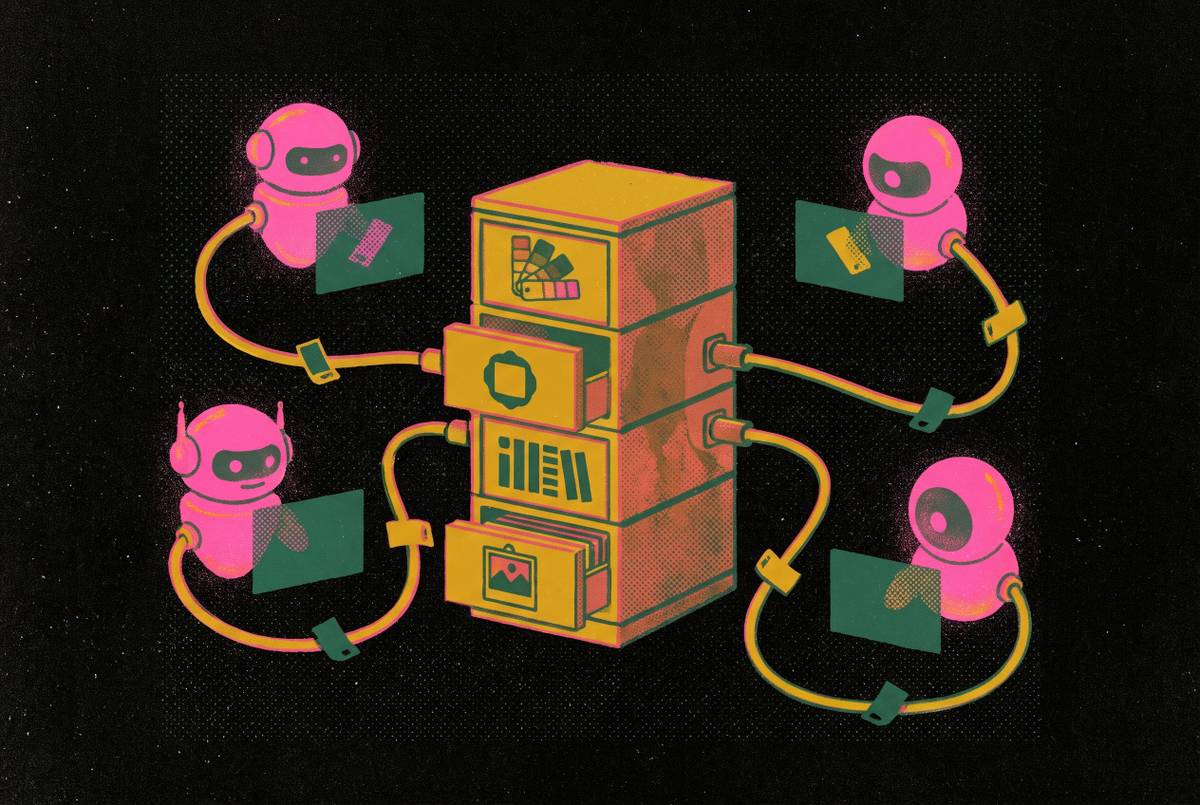
Model Context Protocol, or MCP, supplies the delivery layer through which agents can query the brand contract. An MCP server provides interoperability by exposing structured context and callable functions so that agents can use the same interface to reach the specification. With this architecture, the agent resolves brand context before generation, without having to rely on general training-data knowledge or a description it was given earlier.
The three MCP categories map directly to brand delivery. Resources expose read-only data, including voice guidelines, visual token values, messaging pillars, and restricted terminology. Tools expose functions such as retrieving a brand brief for a channel or validating output against constraints. Prompts provide templated instructions for applying that context to a task. Together, these categories separate the rules themselves from the operations and instructions used to apply them.
For inference-time delivery, the workflow brings current typography rules, color hex codes, copy guidelines, and voice constraints into the model’s context at each prompt execution. For that to happen, the integration must use MCP to resolve the rules afresh. All connected agents can then resolve a server-side brand update on their next call, without maintaining separate brand copies in their configurations.
Access control remains a separate operational responsibility. For teams running more than a handful of agents, the recommended architecture routes MCP traffic through a centralized gateway for policy enforcement, monitoring, and multi-tenant control. This is particularly relevant when agents need different slices of brand context. The NSA’s May 2026 advisory notes that authorization in MCP is optional. Fleet operators must therefore implement deliberate access controls rather than assume the protocol’s defaults establish brand boundaries.
How to make existing brand guidelines usable by AI agents
The practical work begins by translating descriptive guidelines into literal, structured constraints. Teams making that translation should first inspect existing assets page by page and extract hex codes, font names, weight and size pairs, spacing values, corner radius, and logo clearspace. The selection criterion is whether a value specifies an instruction. Strategy paragraphs and creative rationale remain useful to people building the brand, but they do not belong in the constraint set merely because they appear beside an executable rule.
The second step is to name each extracted value by function and structure it as a design token in a shared file. The W3C Design Tokens Community Group specifies JSON files for design tokens, giving this part of the brand contract an established structure.
The third step turns descriptions of voice and copy into clear requirements. Teams should specify preferred terminology, banned words, sentence structure requirements, channel-specific adaptations, and audience-stage messaging variants. Channel conditions make the application of a rule explicit. For example, a social media channel condition can select professional tone instead of asking the agent to decide how an unrestricted tone description applies across every channel.
The fourth step organizes positioning for agent consumption. Named messaging pillars need claims to back them up, and ideal customer profile definitions need approved and banned language and buyer-stage messaging. These steps produce a lean set of structured files, comprising a voice profile, a visual identity reference, and a positioning document. It is not a reformatted brand book. For agencies, the same structure applies separately to each client brand, with a shared query interface and distinct versioned specifications that agents address by brand name.
Why resolution at inference time is the only approach that holds as agent fleets grow
Setup-time brand context creates a drift surface that grows with each agent, task type, and update. Paste-at-prompt-time is the first failure mode. Each agent receives a snippet in its system prompt, so a brand change requires manual updates wherever that snippet appears. The prompt may still work perfectly even when its brand instructions are out of date, so it is easy to miss version fragmentation.
Ingest-at-setup-time produces a different form of the same dependency. Guidelines loaded into an agent’s context or fine-tuning reflect the brand at configuration, with no fresh resolution mechanism. Per-agent brand copies create the third failure mode because each copy must be kept up to date with every change to terminology, color, or voice. The fleet’s size increases the number of places where an update can be missed.
Inference-time resolution removes those independently maintained snapshots as the source of authority. The agent retrieves the declared current specification when the task needs brand context, rather than depending on a local copy that must be synchronized. One server-side release is available to the whole fleet. Each agent picks it up on its next resolution call, so rollout no longer depends on fleet-wide reconfiguration.
Model updates make that separation more important. Frontier model changes can alter how a pasted brand description is interpreted, even when the description itself has not changed. A service contract keeps the constraints outside the model and delivers them at call time, regardless of which model receives them. This does not make generation deterministic. As an evaluation suite provides a durable reference where a demonstration offers only one sample, the brand contract provides a stable basis for checking a non-deterministic fleet.
What the subscription model means for brand governance and agent accountability
Subscription shifts the brand team’s primary control from approving assets to maintaining the specification that produces them. A new color system, a change in voice, or a restricted-terms list is released with its own version. The commit record identifies what changed, when, and by whom. Governance therefore has a concrete object to inspect before a change reaches the fleet, rather than relying principally on corrections after generation.
The specification needs scrutiny for correctness because an error in a shared rule can propagate to every authorized subscriber. Output review then checks whether those constraints do enough and whether the generated work follows them. This changes the purpose of human attention.
Agent authority becomes equally explicit. A social agent can be authorized to resolve voice and copy constraints, while a visual production agent resolves color tokens and typography. Neither needs access to the other’s scope. Mayer Brown recommends recording these boundaries in an “Agent Scope” or “Automation Authority” schedule, connecting technical permissions to the responsibilities agreed between parties.
For agencies, each brand has its own versioned specification and access controls, so an update reaches only that client’s authorized agents and stays out of shared context across the portfolio. Isolation depends on those boundaries being enforced. When output is off-brand, the team first checks what the agent resolved, before looking at what a human reviewer missed. A logged, versioned contract makes that question answerable and gives the review process a specific body of evidence.
Reviewing AI output against the brand contract, not against human memory
A versioned brand specification changes review from a test of familiarity into a check against recorded requirements. Color tokens, typography rules, voice constraints, and restricted terms become the references for findings. Each result names the constraint it checks and says whether the output passed or failed. The reviewer no longer has to rely on a remembered interpretation of the guidelines to explain an objection.
Specific findings make corrective work more precise. “This doesn’t feel right” offers no clear distinction between a violated rule and an unstated preference. “The headline uses a banned term listed in voice-constraints v2.4” identifies both the failure and its authority. That evidence lets the team check whether the output broke a valid constraint or the constraint itself needs to change. The finding is actionable because its reference is explicit.
Version choice is essential to that evidence. If the specification changes between generation and review, the output must be checked against the version the agent actually resolved. Otherwise, review can label compliant output a failure by applying a requirement that did not govern its generation. The review record names the version used for the check.
This distinction becomes more useful as teams review images, video, and copy at volume. Human recall must contend with both growing output and evolving guidelines, while a recorded specification preserves the applicable constraints. Review still assesses the work, but its basis is inspectable. Findings feed back into specification updates, and the next resolution call supplies the revised contract to authorized agents.