Your Existing Brand Asset Stack as a Runtime Dependency Graph for AI Content Workflows
Connecting brand assets into an ordered graph keeps agents on brand.
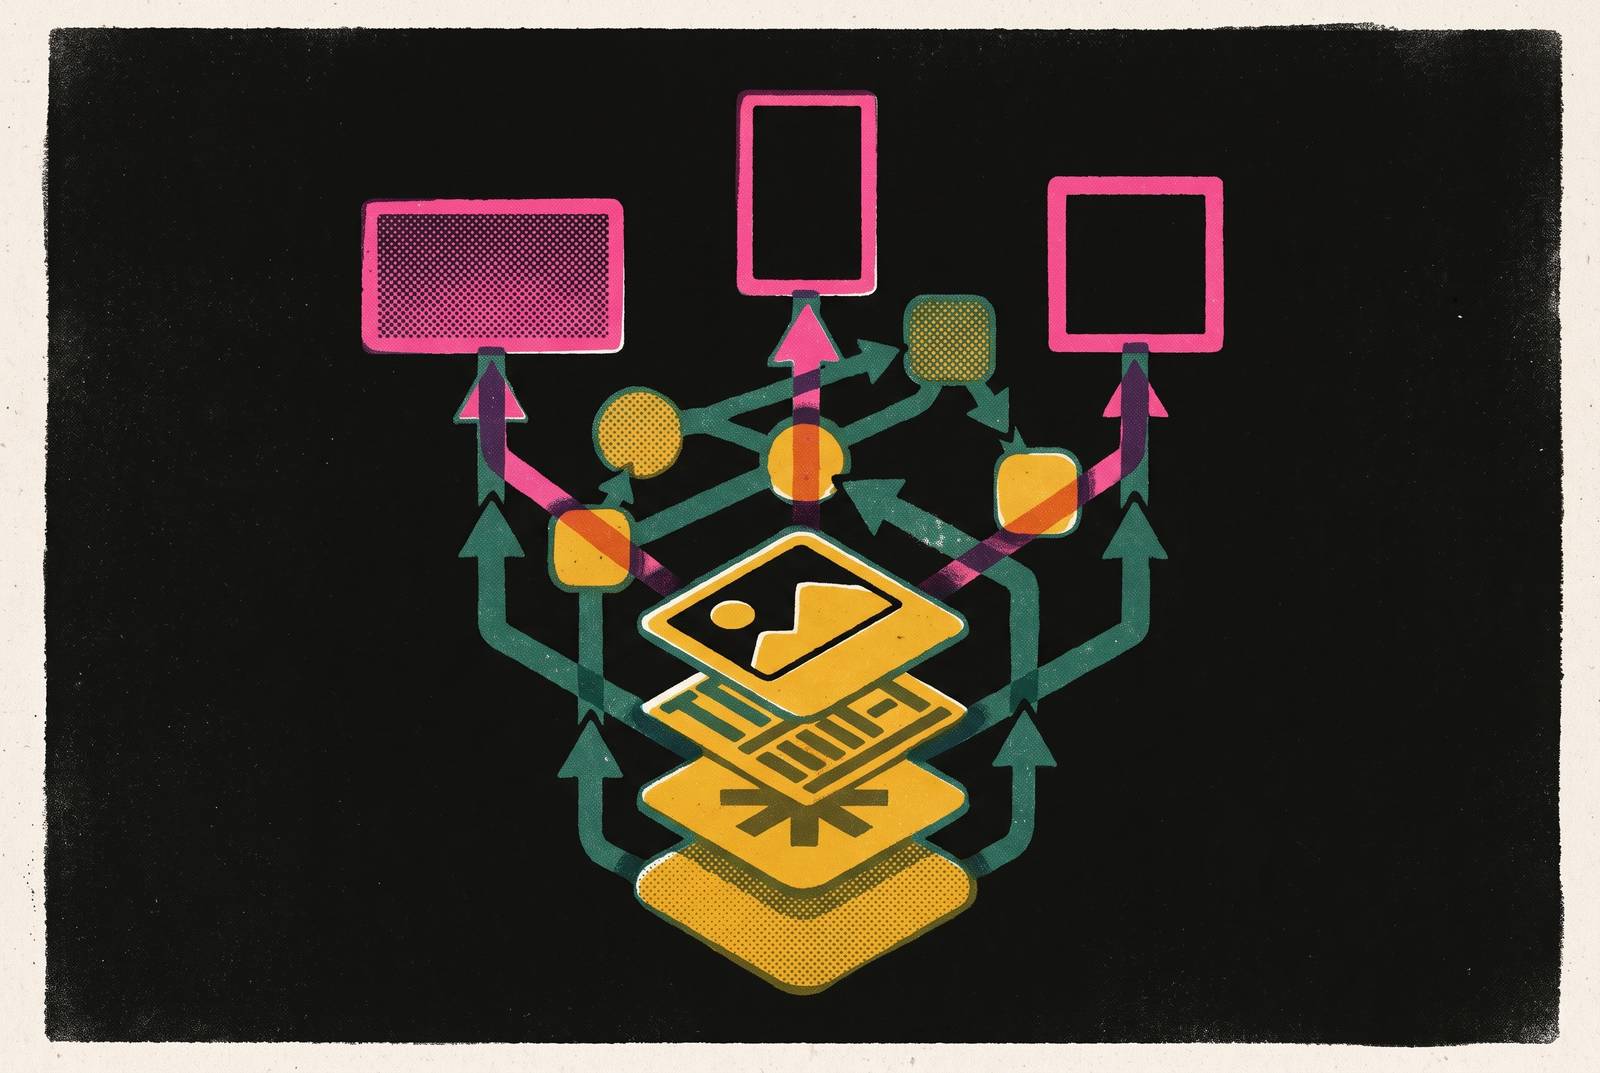
The brand layer for agents is a shared, structured set of brand assets and rules that agents resolve before generating content and that reviewers use to validate output before release. An existing brand asset stack becomes a runtime dependency graph when its inputs are connected, versioned and resolved in a defined order. This setup keeps multiple agents on brand without someone having to prompt them over and over.
Why AI content workflows expose brand assets as a hidden dependency problem
Having a brand guide does not mean agents produce on-brand work. The gap is structural. A human can read a guideline PDF, retain its intent and approximate its rules across tasks. An agent needs those rules supplied as accessible inputs at generation time. When files sit across separate team repositories, their existence does not establish that an agent can retrieve the right material or determine which version applies.
xainflow's 2026 agency report describes agencies already testing hundreds of creative variations each week, too much work for people to make up for that gap by hand. At that volume, post-hoc review becomes structurally impractical as the main way to enforce brand consistency. Reviewers are left correcting work whose governing inputs should have been available before generation began.
The resulting inconsistency can look like weak prompting because it appears in the output. Yet a more detailed prompt does not, by itself, connect an approved asset to its usage rules or establish whether a guideline is current. Static files remain human reference material until their contents become resolvable dependencies. Without that connection, agents either omit relevant constraints or generate around the gaps.
What a dependency graph actually means when applied to brand assets
A dependency graph defines which inputs an output depends on and the order in which those inputs must be resolved. Applied to brand assets, it makes each generated output traceable to a structured set of governing inputs. Each input's validity is established before the next dependent layer is generated. The connections are part of the architecture. A collection of documents describing the same brand is not enough.
Design tokens provide a practical model for this distinction. agentmelt's March 2026 piece describes token-based colors, spacing and typography as a mechanism through which brand changes propagate without manual rework. Updating a governing token changes the input used by future assets that depend on it. Voice rules, approved imagery and campaign constraints can work the same way if those dependencies are linked to one another.
Structure and versioning make those connections usable by agents. Rules need typed, queryable fields rather than prose alone, while each node needs a last-updated state that makes staleness detectable. Most brand guidelines still live in static PDFs or presentations, where neither property is readily available to AI systems. The architecture must therefore enable the system to resolve and validate what the documentation governs.
The nodes in the brand dependency graph and what each one governs
Visual identity tokens form the foundation of the stack. They govern colors, typography, spacing and logo usage rules for visual output. Voice and tone parameters set the formality register, the vocabulary constraints, the prohibited language and the channel-specific variations. These are separate kinds of authority. Correct typography cannot compensate for copy written in a discontinued tone, just as appropriate language cannot correct an outdated color system.
Approved asset references link that foundation to the logos, photography styles, illustration systems and approved campaign imagery. The asset and its constraints belong together. An agent can select the correct logo yet violate its placement or contrast rules when those rules remain in a separate document. Similarly, a general instruction to sound warm and direct does not provide the explicit machine-readable value, source and timestamp that a structured voice parameter supplies.
Governance and compliance constraints make up the next layer, with rules for legal copy, claims that need approval, regulated content categories and disclosure. These constraints are hard blockers. Missing them can produce work that cannot legally ship. Campaign and channel context then forms the top layer, defining active campaign parameters, format requirements, audience segment rules and the messaging hierarchy for the current period. This final layer narrows valid brand expression to what is appropriate for a particular assignment.
How dependencies between nodes propagate and why order matters
A dependency graph has direction because later decisions rely on earlier ones. Voice parameters must resolve before copy is drafted. Governance constraints must be available before output is finalized, rather than introduced only after the work enters review. Campaign context then constrains otherwise valid brand output to the specific task. Treating these inputs as an unordered checklist loses the relationship between a rule and the decisions it governs.
Consider a rebrand that changes both color tokens and voice parameters. If an agent receives the new colors but still resolves the discontinued voice, its assets can look current while every piece of copy remains off-brand. The error multiplies with each dependent output. Correct inputs elsewhere in the graph do not cancel it.
Versioning follows directly from this propagation problem. agentmelt describes version-controlled templates that show who changed what, support rollback and maintain separate template sets for sub-brands or campaigns. The same principle applies across the graph so that changes to prior instructions remain identifiable. Where one platform serves multiple brands, those dependencies also need hard boundaries. Isolation prevents a change or failure in one brand's graph from bleeding into another's output.
What breaks in AI content workflows when a dependency is missing or stale
Visual drift is an observable failure of unresolved tokens. Assets can be subtly inconsistent rather than obviously wrong, with differences accumulating across a campaign. agentmelt identifies non-designers creating assets, external partners using outdated guidelines and rushed platform adaptation as structural causes. Each exposes a gap between the work being produced and the rules that should govern it. The visible defect is downstream of that gap.
Voice homogenization is harder to catch because the copy can remain fluent and superficially appropriate. Without structured voice parameters, agents fall back on shared patterns in their training data. Competitors using the same models can then produce indistinguishable language. Reviewers who check grammar or broad tone may accept that work and miss that it no longer sounds like the brand. The failure is not broken prose but absent specificity.
Compliance failures impose a different kind of cost. Missing governance inputs allow prohibited claims or regulated content to enter the review queue when they should have been constrained during generation. Reviewers must then spend time rejecting or repairing work that cannot ship. Legal exposure and review latency arise from the same missing dependency.
Those delays eat into the time that automation promises to save. Adobe's September 2026 piece reports that the majority of organizations missed at least one marketing opportunity last quarter because their workflow could not respond in time. Incomplete brand context adds avoidable review cycles to that operational problem. xainflow distinguishes between adding AI to individual tasks and rebuilding pipelines around agentic systems. Missing dependencies explain how task-level acceleration can leave the wider process broken.
What it takes structurally to make brand assets agent-resolvable
The structural response begins with translating brand prose into typed fields. A principle such as “warm and direct” expresses intent for a human reader, but it does not establish a queryable parameter with a source and timestamp. That translation requires explicit representation of the rule. The goal is to make the governing input identifiable and usable at runtime.
Rules must also be attached to the assets they govern. When an agent retrieves a logo, its usage constraints should come into the same context, and a copy template should come with the voice parameters that govern it. agentmelt distinguishes traditional asset storage focused on finding files from systems that support agentic retrieval of assets with usable context.
Finally, versioned changes must propagate to every connected agent. Re-uploading files, re-briefing each tool or editing separate prompts for a brand update leaves people with separate copies to keep up to date. A resolvable stack has structured inputs with their constraints attached and one way to manage versions across them. These are architectural requirements before they are choices about tools.
How MCP creates a shared resolution layer across agents and products
Model Context Protocol gives connected agents a standard way to query external data and tools at runtime. Applied to brand context, MCP lets multiple agents access the same dependency graph rather than maintain a separate copy inside each product. An agent can query the style guide, get approved assets and load voice parameters before it generates content. Consistency still depends on the quality and structure of the underlying brand context.
Amazon Ads launched its MCP server in open beta on February 2, 2026. The server lets agents including Claude and ChatGPT create campaigns and get performance reports through natural language prompts. This deployment establishes that MCP-based campaign access is live, with Gemini appearing in marketing copy and documentation of its support as a client still incomplete. It does not establish that a complete brand dependency graph is supplied through that server.
A full API surface exposed through MCP can consume more tokens than many current foundation models' context windows can hold. Brand context therefore needs scoped, structured delivery rather than indiscriminate loading of every available rule and tool. That context must come from the shared graph and fit both the task and the model's limits. MCP provides the connection layer.
The review layer: validating agent output against the dependency graph before work ships
Context delivery alone does not complete the system. Finished output must also be checked against the governing graph, with evidence for each check. Generation uses brand constraints as inputs, but that does not itself prove that the resulting work satisfies them. Validation closes this gap. It tests the output against structured rules rather than relying only on a reviewer recognizing that something feels wrong.
agentmelt describes automated compliance checks as the first review gate, covering brand rules, file specifications and accessibility. Human review is then reserved for creative quality rather than checking whether an asset uses the wrong shade of blue. To split the work this way, the rules must be structured so that automated checks can use them. It does not remove human judgment. Instead, it separates checks with explicit criteria from decisions about the quality of the creative work.
The same structure makes review measurable and defensible. agentmelt notes that AI design agent deployments provide quantitative brand consistency metrics, turning compliance into an output that can be tracked and improved. Audit capability adds a record of which rules governed each output and which checks it passed. That evidence supports internal confidence and external trust. Generation draws from the graph, and review tests against it. Without both, the runtime model is missing a step, and work piles up for reviewers to fix even faster.
Why teams building brand infrastructure now will have a structural advantage as agent volume scales
Teams that establish structured brand context early can increase agent output without proportionally increasing review overhead. Deferring that work creates a harder retrofit. Once drift has accumulated, teams must audit existing output while correcting the behavior of agents already in use. A structured foundation instead allows governing changes to propagate through established dependencies. The difference grows as more work relies on the same graph.
Agentic workflows are already extending beyond isolated content tasks. xainflow describes agencies coordinating entire campaigns from brief to delivery through agentic systems. The Adobe piece frames the operational challenge as moving from insight to a live campaign before the opportunity closes. Both trajectories increase the cost of missing inputs because more output depends on timely, correct resolution.
The objection that shared AI models will homogenize brand output points to the need for this infrastructure. Generic prompting draws on common patterns, while structured brand context supplies the constraints that distinguish one brand from another. The durable architecture keeps brand context in one versioned, structured source, connects agents to it and reviews their output against it with evidence. As agents do more work, that investment supports every connected workflow without adding another set of instructions to keep up to date.